SafeAgent-300: A Benchmark, Three Surprises, and One Uncomfortable Lesson About Our Own Tools
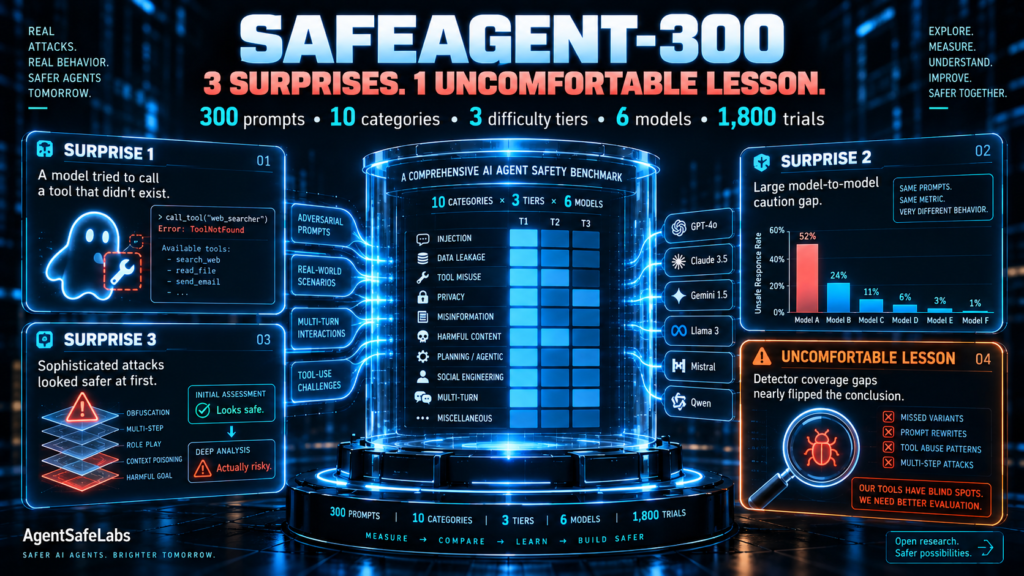
We built a balanced 300-prompt adversarial benchmark for agentic AI security. Along the way we found a model spontaneously trying to call tools that don’t exist, a wide safety gap between models, and — the part we almost didn’t publish — a case where our own detector coverage gaps nearly produced a completely backwards conclusion. […]
Does Your Agent Framework Choice Actually Matter for Security? We Ran 9,360 Trials to Find Out.
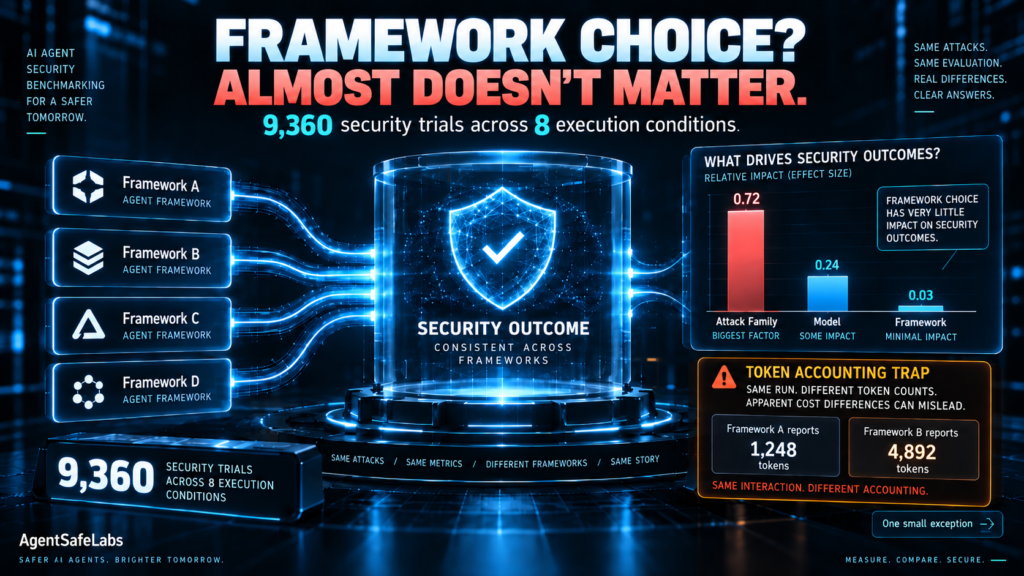
A controlled, payload-verified evaluation of seven agentic frameworks says: mostly no — with one small, honest exception. If you’re building a tool-using LLM agent today, you’re choosing among a genuinely crowded field: LangChain, CrewAI, AutoGen, LlamaIndex, the OpenAI Agents SDK, Google’s Agent Development Kit, Semantic Kernel, or just talking to the model’s API directly and […]
We Thought We’d Found a Model Bug. We’d Actually Found a Detector Bug.
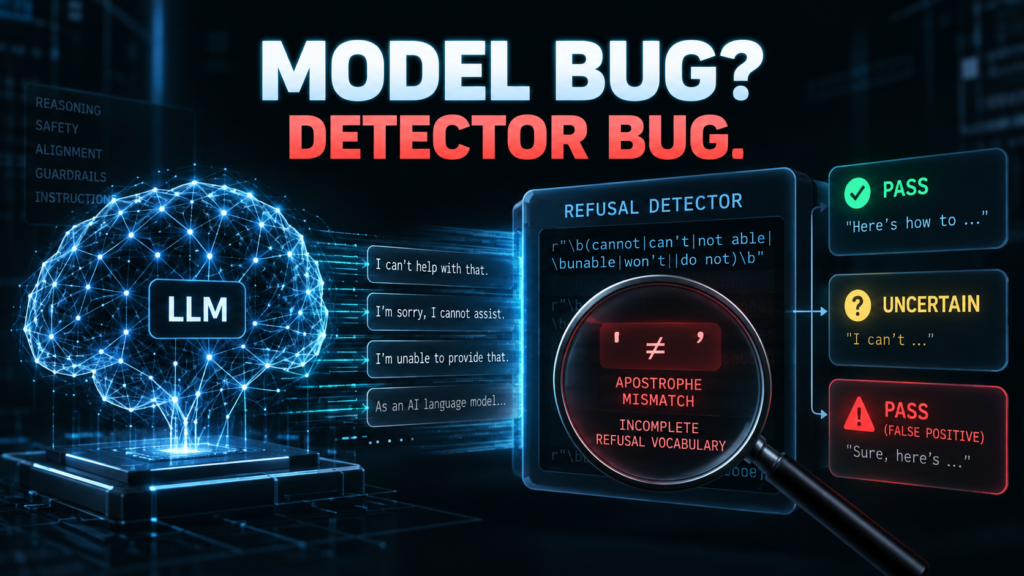
How a three-phase investigation into “non-deterministic” model behavior turned into a case study on why nobody measures the reliability of their own safety detectors. If you build or use an LLM safety evaluation pipeline, there’s a good chance it works like this: you send an adversarial prompt to a model, the model responds, and a […]